A Cornell research team has won a $10 million, multiyear award to develop tools that help communities manage public discussion and independently test the artificial intelligence systems taking part in it.
The Laude Institute selected "Rebuilding Trust: Civic Discourse Infrastructure for Auditable AI" as one of four Moonshot award winners after a six-month development period, according to Cornell.
The work was described in the institution's report.
Community control and independent checks
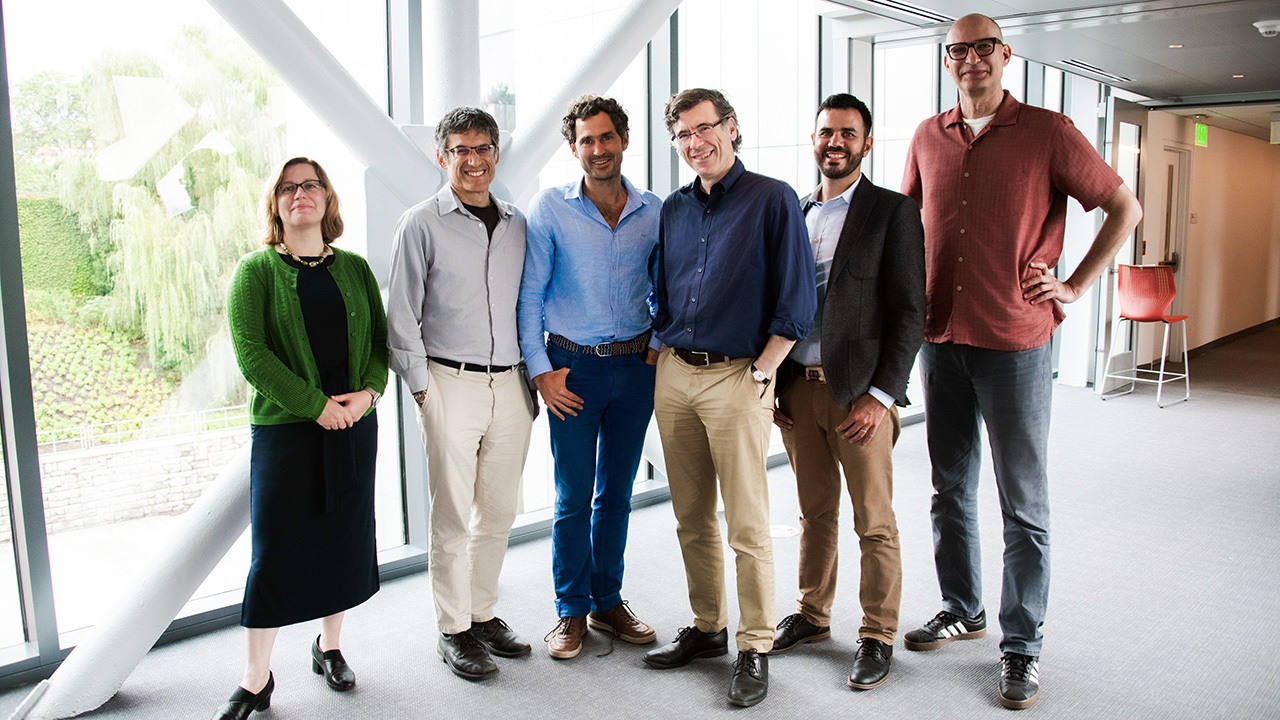
Cristian Danescu-Niculescu-Mizil leads the project with Jon Kleinberg, David Rand, Natalie Bazarova, Robert Kleinberg and Mor Naaman, joined by 11 students.
The team received the award Oct. 29 in San Francisco after being named one of eight finalists and receiving $250,000 in seed funding in April.
During the intervening months, researchers built prototypes, held workshops, interviewed prospective users and tested deployment approaches.
Their proposal addresses a problem that extends beyond detecting inaccurate posts: Communities need ways to set the rules governing AI participants and check whether systems follow those rules.
The researchers aim to make interventions transparent and accountable rather than ask communities to accept a system's promised behavior on trust.
Four connected tools
An Assistant Toolkit would let communities configure and test AI assistants for their own needs, according to Cornell's account of the project.
ConvoCompass is intended to help editors and communities navigate disputes over rules and policy.
ConvoArena and a Simulation Factory would provide settings for tests involving people and simulated interactions before tools are used more widely.
An Auditing Benchmark would support independent evaluation of whether an AI system's actions match its declared behavior.
Together, the tools are intended to provide infrastructure for civic discussion as AI becomes more capable of impersonating people and generating persuasive material.
Another winning effort has Cornell ties
JupyterHealth, a separate Moonshot winner involving the University of California, Berkeley, and the University of California, San Francisco, also includes a Cornell connection.
JP Pollak, affiliated with Cornell Tech and Weill Cornell Medicine, is a co-leader of that effort.

FingerLakes1.com is the region’s leading all-digital news publication. The company was founded in 1998 and has been keeping residents informed for more than two decades. Have a lead? Send it to news@fingerlakes1.com.